NewMusic
 TRACK
Sound
The Inference Engineering Masterclass — Philip Kiely & Ali Taha, Baseten
1:41:29 duration0 plays0 favoritesMedium quality
Play now
About this track
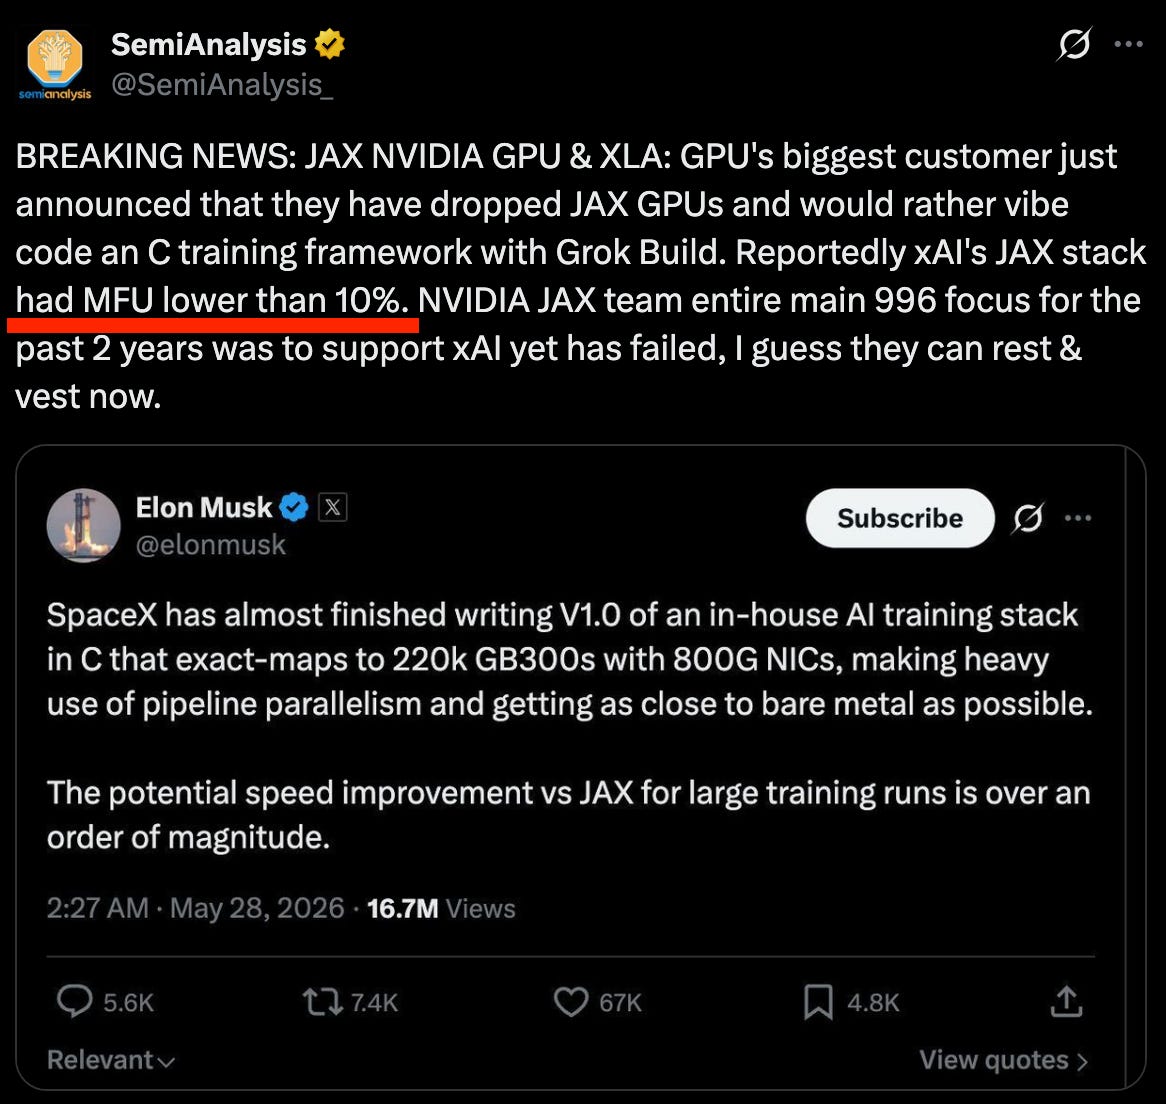
Watch the full episode on YouTube:We first covered Baseten last year when DeepSeek mania was at peak hype. Now they have raised a monster $13B round and become one of the new cohort of AI Infra decacorns that are (with Nvidia, Intel, and the semis complex) chief beneficiaries of the Inference Inflection. We return to Baseten at the peak of the 2026 edition of Open Weights debate. Ali has published a viral breakdown of Kimi K3:And since you last saw him, Philip has spoken at AI Engineer and written the definitive book on Inference Engineering spotted all over SF:Three years ago, inference engineering barely existed as a category.Today, it is one of the most critical disciplines in AI. Inference engineering inherently tackles a different question than standard model training: “How do you turn those weights from training into a product that is fast, reliable, and affordable at scale?” Focusing on these creates an entirely new optimization problem.In one recent GLM-5.2 experiment, quantizing more of the model actually preserved its benchmark quality while increasing throughput by 20%, because the errors introduced in different layers could cancel each other out.Inference is no longer just the final step after training. It is becoming its own engineering discipline, with its own research problems, infrastructure, and increasingly specialized roles.In this episode, Baseten’s Philip Kiely and Ali Taha join swyx and Vibhu to explain what actually happens after a new open model is released and what it takes to turn “we generated a token” into a fast, reliable, production-ready API.We go deep on cache-aware routing, disaggregated prefill and decode, quantization, speculative decoding, KV-cache movement, model parallelism, GPU kernels, and the race to make frontier models up to 10× faster. Philip and Ali explain why inference optimizations can still produce gains of 20%, 100%, or even 200%; how quantization errors can cancel one another out; why identical weights can behave differently across clusters; and how Baseten graft
From the album
 Latent Space: The AI Engineer Podcast25 tracks · Track 21
The podcast by and for AI Engineers! In 2025, over 10 million readers and listeners came to Latent S...
→More By Latent.Space...
You may also like